Best Practices for Instructional Designers
Instructional designers working in Outdoo AI are not building content to be consumed — they are building scenarios to be practiced. The design challenge is different. This guide covers what makes a roleplay agent behave realistically, how to write scorecards that produce useful data, and how to structure simulations that transfer to live performance. It focuses on the why. For a quick reference of where each setting lives in Outdoo AI, see the Mastery Cheat Sheet for Instructional Designers.
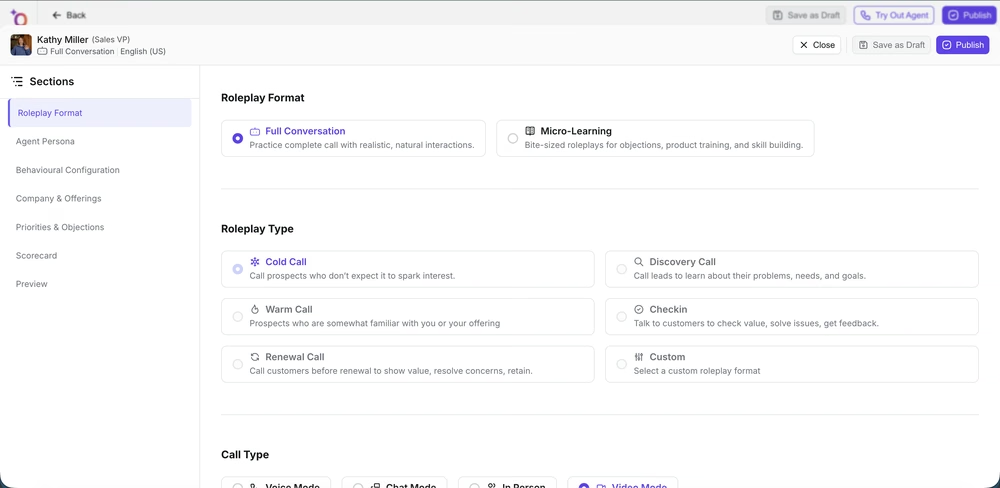
Designing roleplay agents
Realism is the only thing that matters
A team member who passes a practice session against a predictable, easy-to-handle AI agent has not developed a skill. They have gotten comfortable with a simulation that does not resemble their actual job. Every design decision in a roleplay agent should serve one question: does this feel like a real buyer?
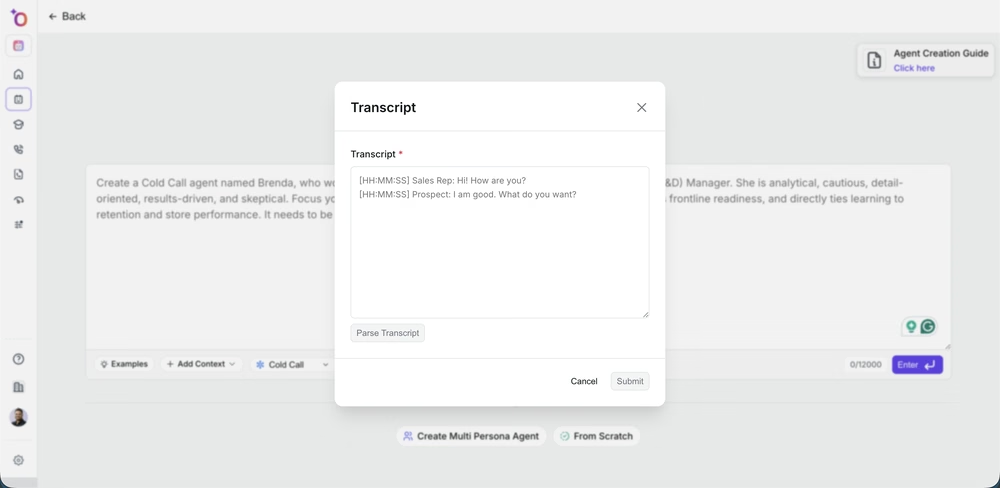
Start from a real call, not a persona document
The best agents come from actual customer calls, specifically the hard ones. Upload a call where the team member lost momentum, where a new objection surfaced, where the buyer was unusually skeptical. Outdoo AI generates an agent from that interaction. Team members practicing against it are rehearsing for the actual situation, not a textbook version of it.

Write persona descriptions that constrain the AI specifically
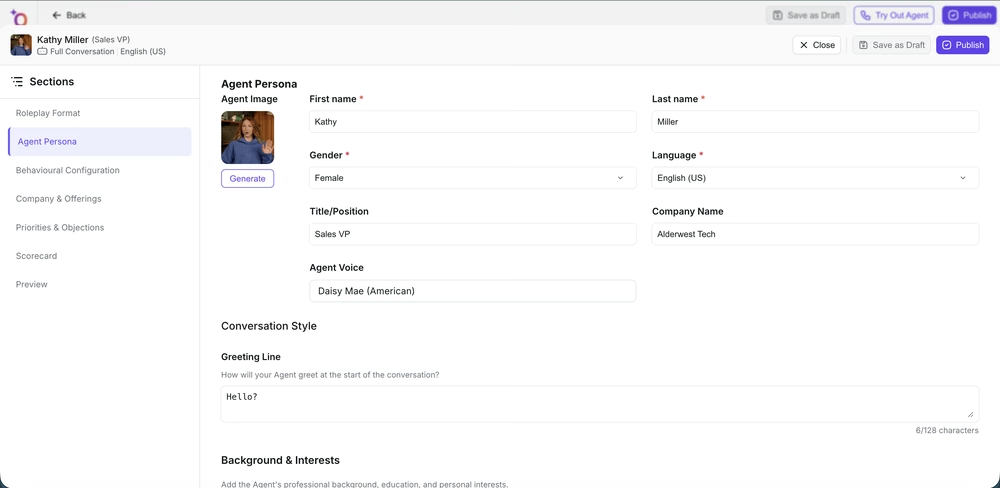
Vague personas produce inconsistent agents. "Skeptical buyer" is not a persona — it is an adjective. A useful persona specifies:
- Role, seniority, and company context (VP of Sales, 200-person SaaS, currently using a competitor)
- Emotional starting state (frustrated from a bad prior vendor experience, or cautiously interested)
- What they know and what they do not (aware of the problem, not aware your product exists)
- The specific objections they will raise and in what order (leads with budget, then circles back to integration concerns)
- What would make them more open (a specific ROI framing, a specific proof point they find credible)

Use scenarios to set the buyer's starting state, not just their role
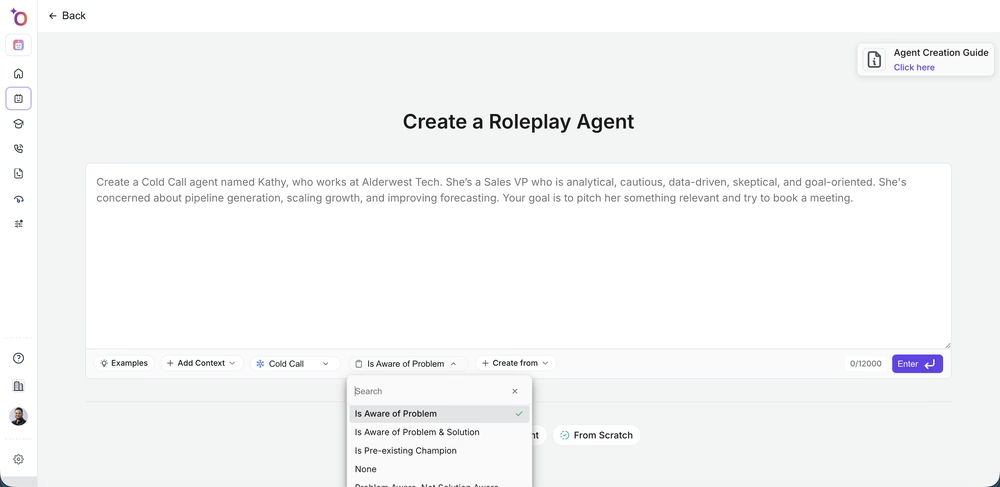
A VP of Sales who is actively evaluating solutions behaves completely differently from a VP of Sales who does not know they have a problem. The persona describes who they are. The scenario describes where they are in their journey. Both are required for a realistic simulation.

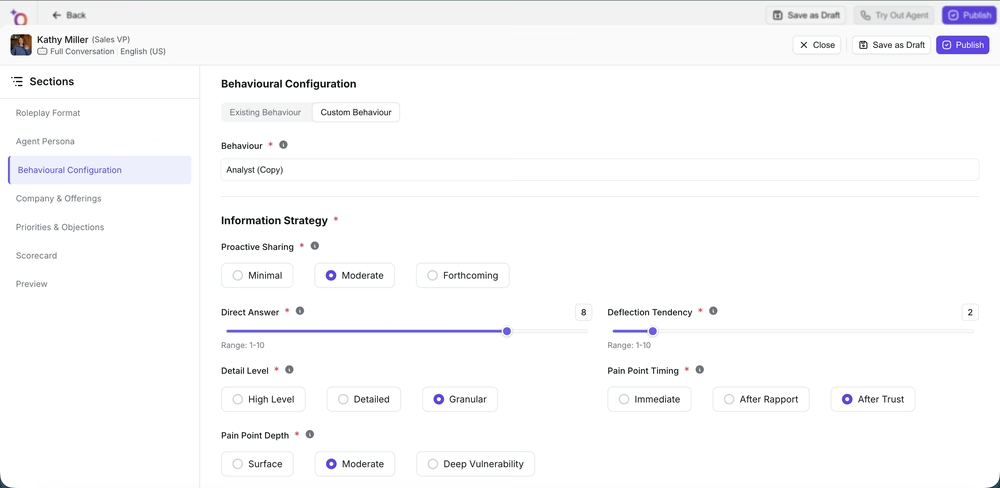
Configure behavior constraints, not just personality
The behavior settings let you control how the agent responds to different team member actions: how resistant they are to pivots, whether they ask follow-up questions or just answer, how quickly they reveal objections, and what triggers their interest. These settings make the difference between an agent that feels like a real conversation and one that feels like a quiz.
Add resources to the agent to ground it in your actual content
If you have battlecards, product briefs, or objection-handling guides, attach them as resources. The agent uses these to ensure its responses and objections align with what your team members have been trained on, not generic sales objections from its training data.

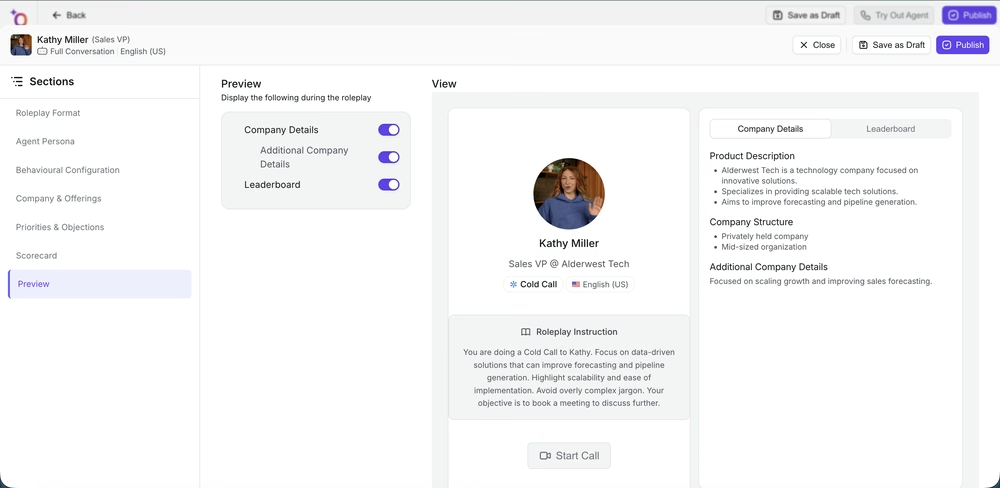
Always preview before publishing
Run the agent yourself before assigning it to team members. Test specifically: does the AI stay in persona under pressure? Does it raise the objections you configured? Does it respond appropriately when the team member gives a good answer? An agent that behaves inconsistently in preview will behave inconsistently in practice.
Designing scorecards
Score the behavior, not the outcome
The most common instructional design mistake in Outdoo AI scorecards is measuring what happened rather than how it happened. "Did the team member set a next step?" is an outcome. "Did the team member confirm the next step using the buyer's own calendar availability?" is a behavior. Scoring behaviors gives you a cause. Scoring outcomes gives you a result you already knew from the CRM.
Every criterion maps to a specific playbook behavior
Before writing a scorecard criterion, find the corresponding line in your sales playbook or call guide. If you cannot point to a specific, documented behavior the team member is expected to demonstrate, the criterion does not belong on the scorecard. Scorecards should be a machine-readable version of your playbook, not a list of general sales skills.
Write one behavior per checklist point
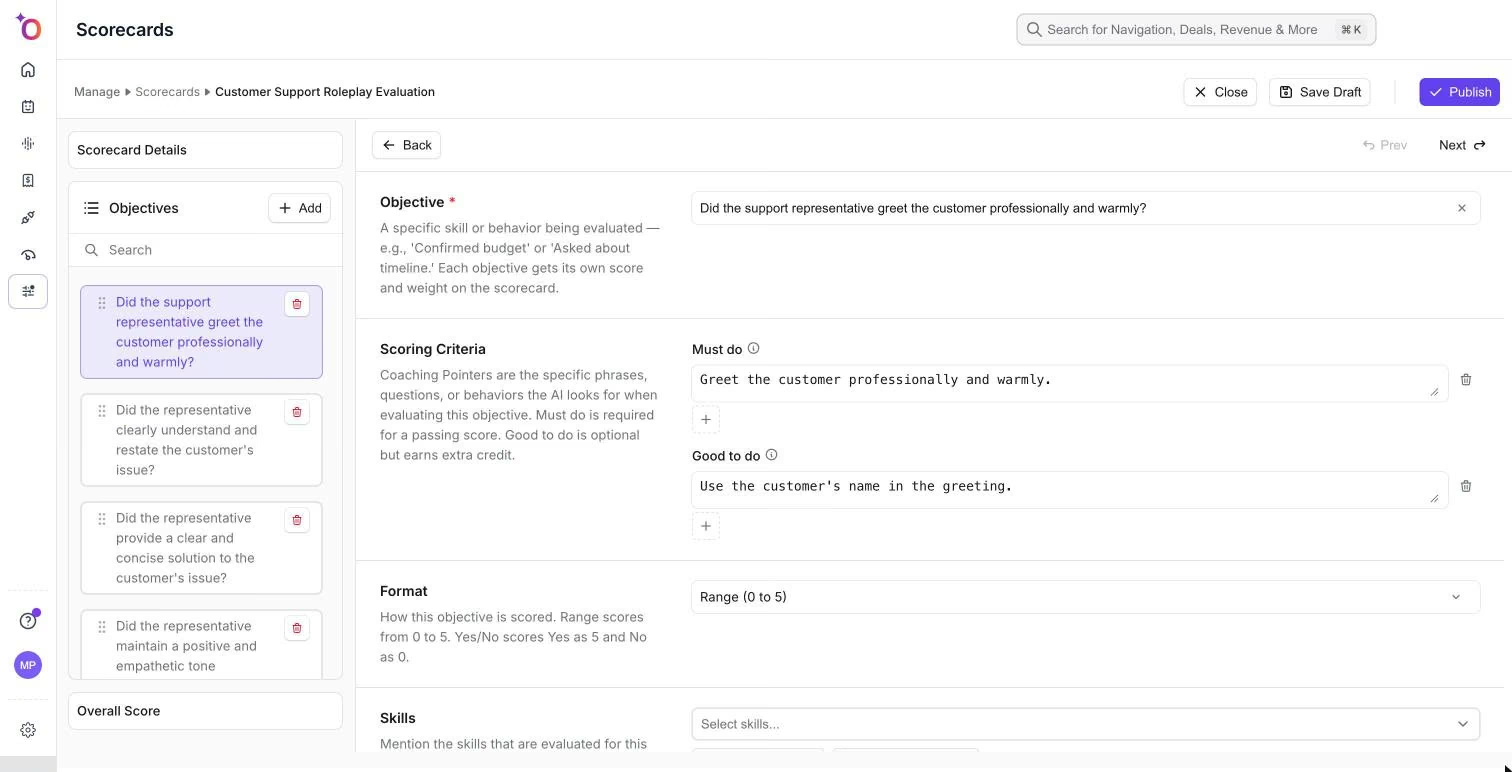
New scorecards use the Caliber 2 scorecard model, where Must do and Good to do are lists of separate points and the score is calculated from how many points are met. A point that bundles three behaviors can only be met, partly met, or missed as a whole, so the score loses detail. Split it into three points. Put the behaviors that a passing performance needs under Must do, and the ones that show mastery under Good to do.
Decide when an objective does not apply
Some objectives only make sense on some conversations. Handling a pricing objection cannot be scored if the buyer never raised one. On Caliber 2 scorecards, use When to mark N/A to describe when the objective should be left out of the score, for example "Mark N/A if the customer never raises an objection". Use the Yes (5)/ No (0) format for checks that are simply done or not done, and keep Range (0 to 5) for behaviors with degrees of quality.
Use the distribution settings to weight what matters most
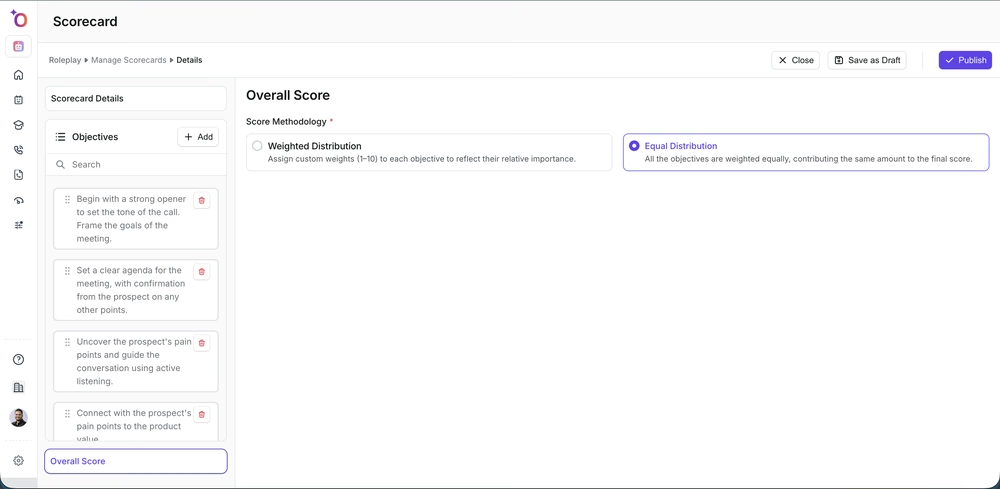
Not all criteria carry equal weight. Discovery question quality may matter more than talking speed for your team. In the scorecard's Overall Score section, choose Weighted Distribution and give each objective a weight from 1 to 10 to reflect actual priorities. A criterion worth 5% of the score will not change coaching behavior, even if it appears on the card.
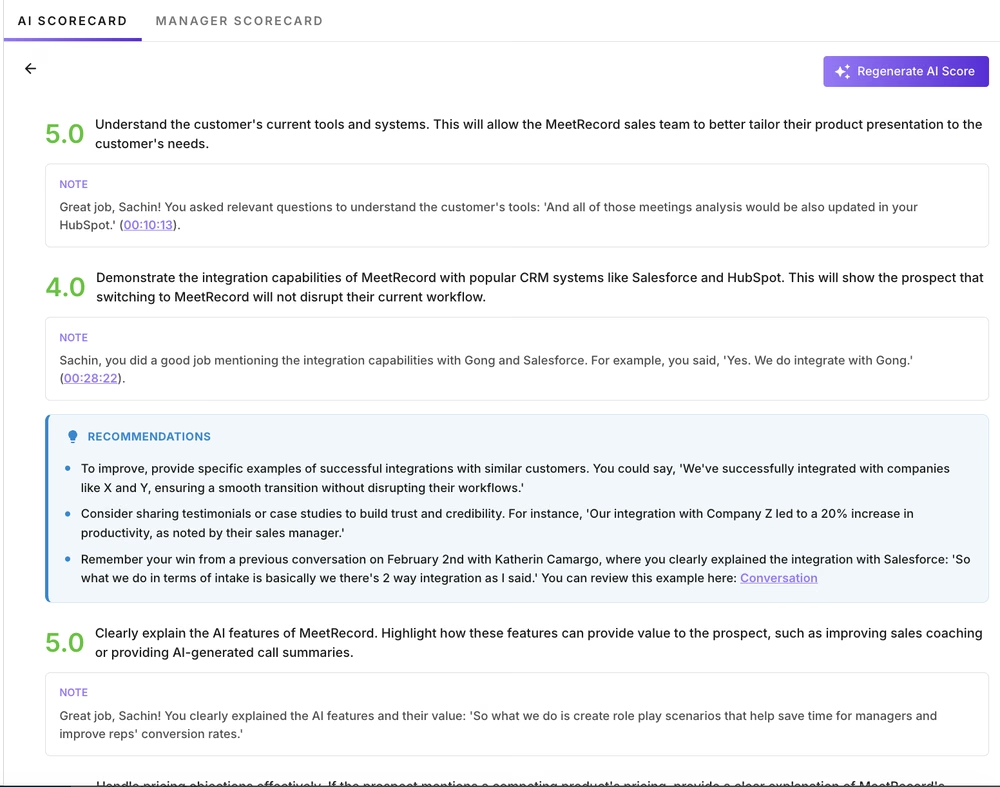
Use the same scorecard for roleplay and live calls
Outdoo AI applies your scorecard to both practice and real conversations. This consistency is what makes training data meaningful — you can compare a team member's discovery score in roleplay to their discovery score on real calls. Different scorecards for practice and live breaks this comparison and removes the signal you need to measure transfer.
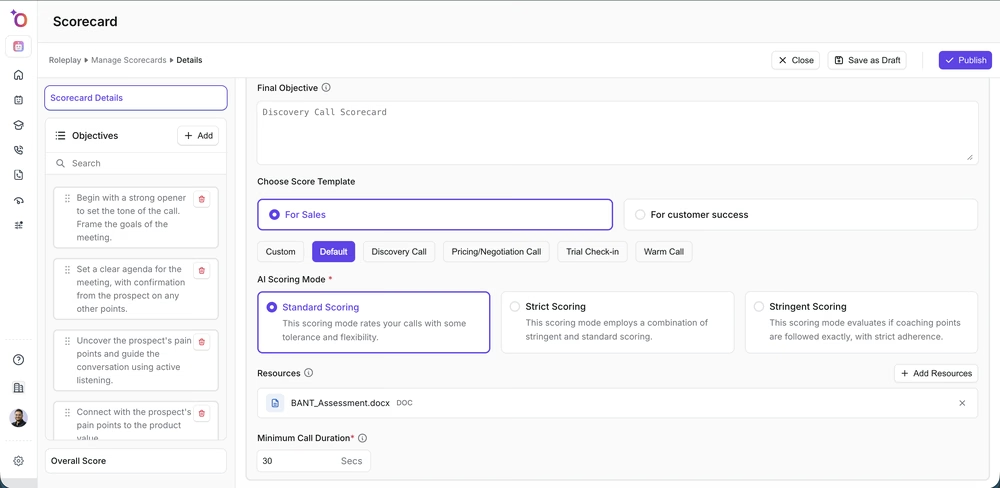
Attach resources to the scorecard for in-context coaching
You can attach a reference document directly to a scorecard, such as an objection-handling guide or talk track. The AI uses it when scoring, so feedback reflects the standard your team was actually taught rather than generic advice. This narrows the gap between "I got a low score" and "I know what to do differently."
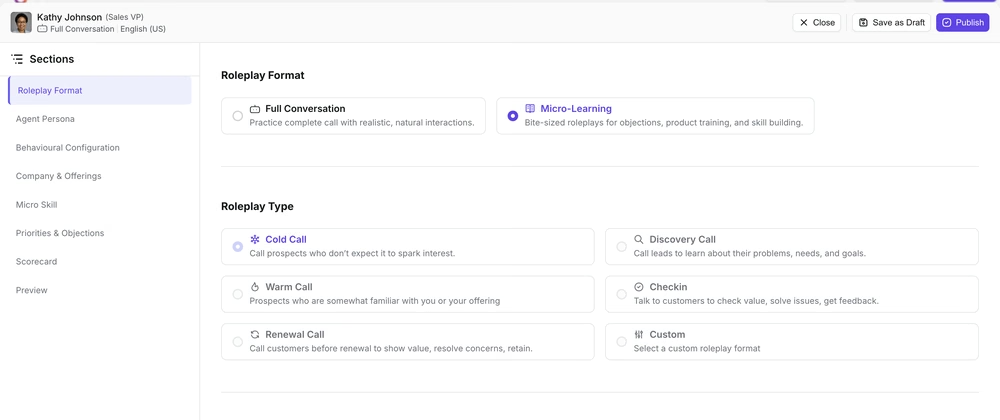
Designing micro-learning agents
Use micro-learning for targeted reinforcement, not initial learning
Micro-learning agents drop team members into a single moment, such as the pricing objection, the next-steps ask, or the competitive differentiation question, and score them on just that moment. They are not replacements for full-call roleplay. They are reinforcement tools: use them after a full training program to maintain and sharpen specific skills, or during a call blitz to drill one skill fast.
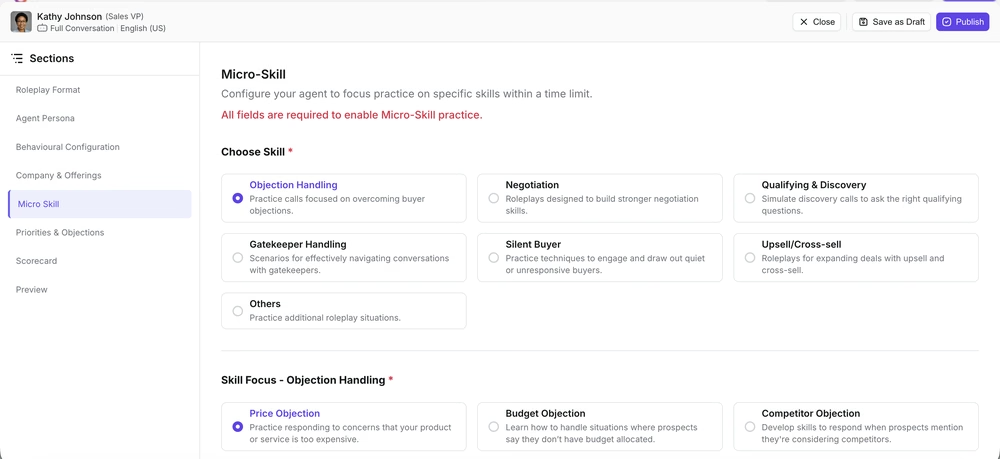
Keep micro-learning agents under 3 minutes
A micro-learning agent that runs longer than 3 minutes is a full roleplay with a different name. The value of micro-learning is that it fits into a gap in the day. Design them to start at the relevant moment, handle 2–3 exchanges, and end. If the scenario needs more than that to make sense, it belongs in a standard agent.
Designing workflow simulations
Document the correct path before you record
Know the exact sequence of actions, every field, every click, every screen transition, before you hit record. Walk through the real workflow yourself and write it down step by step first. The most common cause of simulation data quality issues is an ambiguous or incomplete correct path, since your recording becomes the ideal run every attempt is scored against.
Prioritize business-critical steps when reviewing results
Outdoo AI does not let you assign different weights to different steps. Workflow results show adherence (which required pages were visited or missed), backtracking, and time against the ideal recording, but they do not rank one missed step above another. When you review results, put your attention on the steps that carry real business risk. A missed required field that breaks a downstream process or causes a compliance issue matters more than an optional field left blank, even though the report treats them the same. Team members should hear that distinction from you in coaching, since the tool will not make it for them.
Keep each simulation to a single workflow
One simulation per workflow, not one simulation covering all post-call tasks. A 20-step simulation covering the entire CRM update process gives you aggregate accuracy. A 6-step simulation covering just the opportunity stage update gives you specific data on exactly where errors happen. Build small and specific. You can always add more simulations.
Remember that omissions get caught automatically, but not weighted
The most common mistakes in post-call workflows are not doing the wrong thing — they are not doing a required thing at all. Outdoo AI's comparison with the ideal recording catches much of this on its own: a workflow's results list missed pages and flag backtracking, with no setup required on your part. What it will not tell you is which omission actually matters. A team member who skips an optional note field and a team member who skips a mandatory disposition field can look similar in the results. Treat those very differently in coaching, since the report will not make that distinction for you.
Testing and iterating your designs
Run agents and simulations yourself before any team member does
Walk through every piece of content you build as if you were the learner. For agents: does it feel like the right buyer? Does it raise the objections you intended? For simulations: does the interface match the real system closely enough that practice transfers? You will catch design problems in five minutes that would take weeks to surface in team member feedback.
Use early cohort data to improve design, not just measure performance
The first cohort through any new program reveals instructional design gaps. A low score on a specific scorecard criterion might mean team members lack the skill, or it might mean the agent is not testing for that skill effectively, or the criterion is ambiguously written. Investigate before drawing conclusions from the data.
Hope this article was helpful. For any queries, please write to support@outdoo.ai
Related articles
- Mastery Cheat Sheet for Instructional Designers: quick reference of where each setting lives